Cut hold times to zero: 24/7 AI phone support
You cut hold times to zero by having an AI voice agent answer every call on the first ring, resolve routine tier-1 questions end to end, and absorb spikes and after-hours volume that would otherwise queue. The calls that genuinely need a person get a warm, context-rich transfer instead of a wait. Here's how to design it.
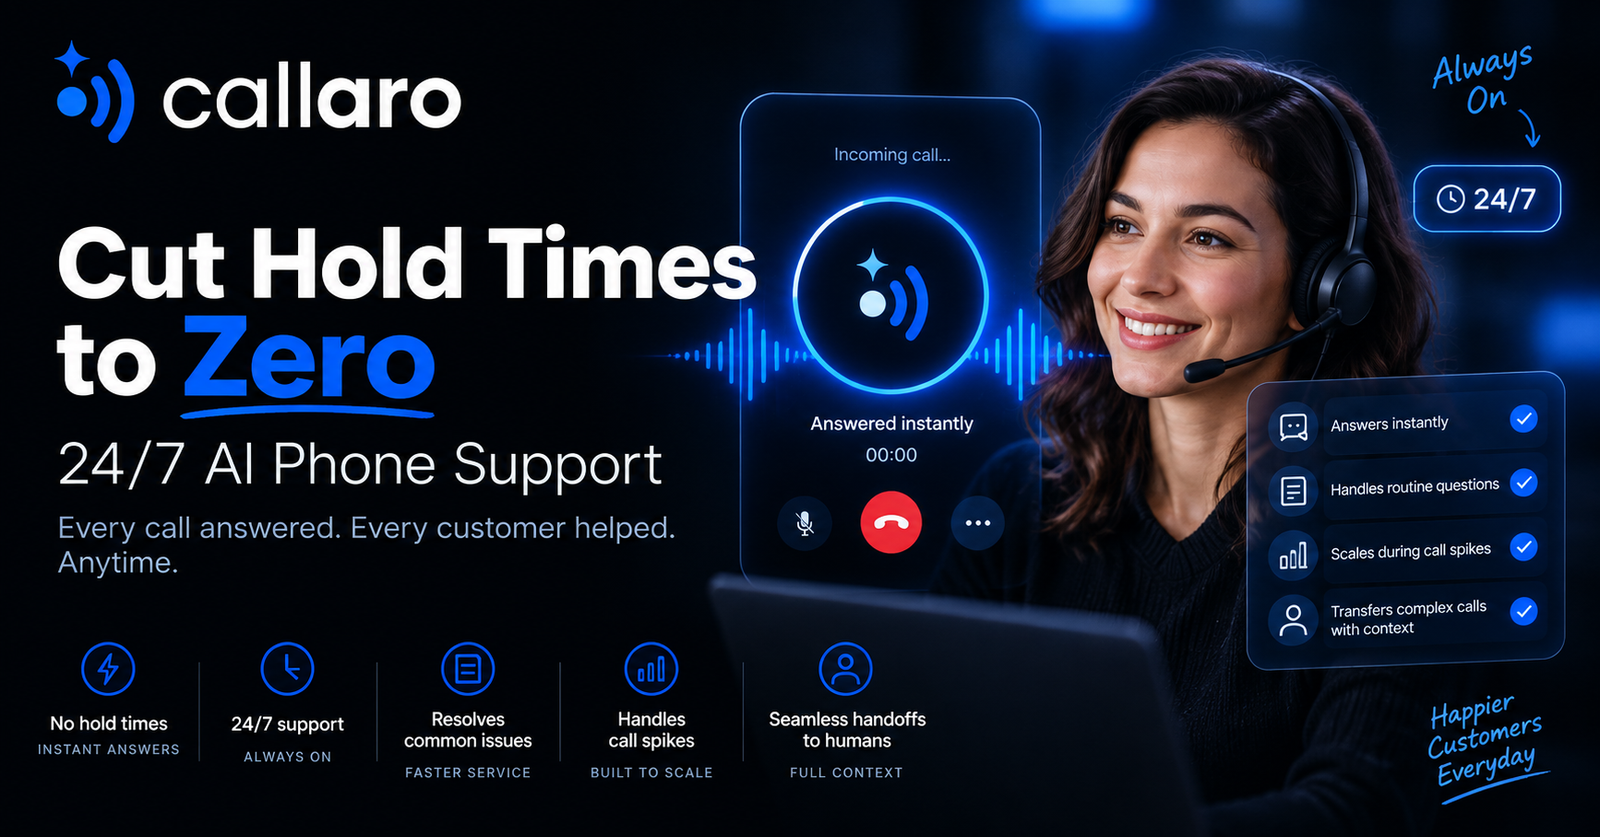
You cut hold times to zero by making sure no caller ever waits in the first place: an AI voice agent answers every call instantly, resolves the routine questions that make up most of your volume, and absorbs the spikes and after-hours calls that used to build queues. The minority of calls that truly need a human get a warm, context-carrying transfer instead of hold music. Hold time isn't reduced — it's designed out.
This is a playbook for standing up 24/7 AI phone support that customers actually like. For the fundamentals of how these agents work, see our complete guide to AI voice agents.
Why hold time exists — and why AI removes it
Hold time is a capacity problem. Calls arrive in bursts; human agents are a fixed, expensive resource; when arrivals exceed capacity, callers queue. Every traditional lever — staffing to peak, IVR trees, callback offers — is a compromise that either costs too much or annoys people.
An AI voice agent breaks the constraint because it scales with concurrency, not headcount. When a hundred calls land at once, a hundred agents answer at once. There is no queue to build because there is no fixed pool to saturate. That's the structural reason AI support can take hold time to zero where an IVR merely reshuffles the wait. If you're weighing this against a phone tree, our comparison of voice AI vs IVR lays out the difference.
Start with tier-1 deflection
The fastest win is resolving the calls that don't need a human at all. In most support lines, a large share of volume is a handful of repetitive tier-1 questions: order status, business hours, password resets, balance or plan checks, appointment scheduling, "where is my delivery." These are structured, high-frequency, and low-nuance — exactly what an AI agent handles end to end.
The key is that resolving means resolving, not deflecting to a menu. Wire the agent to your real systems so it can look up the actual order, reset the actual password, book the actual slot — then confirm the outcome to the caller. A bot that says "visit our website" isn't containment; it's a bounce. Real integration is what turns tier-1 volume into genuine self-service. This is the same orchestration that lets agents take real actions mid-call — see how we orchestrate calls and tools.
Cover the hours humans can't
A support line that's only staffed nine to five leaves nights, weekends, and holidays as dead air or voicemail. For a global customer base, someone is always in business hours somewhere. 24/7 AI coverage means:
- After-hours calls get resolved, not queued for tomorrow. A customer at 2am gets their order status now, not a callback next business day.
- Overnight tier-1 resolution reduces the morning backlog your human team walks into.
- Emergencies and high-priority issues can still reach a human via an on-call escalation path, while everything routine is handled automatically.
This alone often justifies the deployment: you extend coverage to all hours without hiring three shifts.
Absorb spikes without staffing to peak
Support volume is spiky — a product launch, an outage, a billing run, a viral moment. Staffing to peak means paying for idle agents most of the time; staffing to average means brutal hold times when the spike hits.
AI overflow solves this. Route calls to the AI agent first, or overflow to it the moment human queues exceed a threshold, and the spike gets absorbed by concurrency instead of building a queue. The agent handles what it can, and hands the rest to humans as capacity frees up. Your human team stays sized for the steady state while the AI takes the peaks. Concurrency and overflow routing are campaign-level controls precisely because the right thresholds differ by line and season.
The operational win compounds over time. Because the AI never gets overwhelmed, tired, or short-staffed, your service level stays flat through the events that historically produced your worst customer experiences — the launch day, the outage, the Monday-morning surge. Instead of scrambling to pull agents onto phones and apologizing for two-hour waits, the spike is a non-event. That predictability is worth as much as the raw cost saving, because it removes the days when your support reputation used to take its biggest hits.
Warm transfer with context
Some calls should reach a human — and when they do, the handoff makes or breaks the experience. Nothing frustrates a customer more than explaining their problem twice.
A warm transfer carries context: when the agent escalates, the human should receive who the caller is, what they've already tried, the relevant account details, and a summary of the conversation so far. The agent has already done the identification and triage; the human picks up mid-context and resolves, rather than starting from "how can I help you today?" Done well, an AI-fronted line makes your human agents more effective, because every call that reaches them is pre-qualified and pre-summarized. The same discipline powers a good outbound handoff — see AI cold calling that converts.
Escalation rules: know when to hand off
Containment is a goal, not a religion. The wrong instinct is to make the AI cling to every call; the right design escalates fast when it should. Build explicit escalation triggers:
- Intent the agent isn't scoped for — a complaint, a cancellation with retention stakes, a complex billing dispute.
- Detected frustration or repeated failure — if the caller is upset or the agent has failed to resolve after a couple of attempts, transfer rather than loop.
- Explicit request — "let me talk to a person" should always work, immediately, with no maze. Fighting this is the fastest way to a bad reputation.
- High-value or high-risk cases — VIP accounts, safety issues, anything where a wrong answer is costly.
Good escalation rules are what let you push containment high without degrading experience, because the calls that need empathy or judgment get it.
Measuring CSAT and containment
Two numbers anchor an AI support program, and they must be read together:
- Containment (or resolution) rate — the share of calls the AI fully handled without a human. High containment cuts cost and hold time, but only counts if the issue was actually resolved, so measure successful containment, not just "didn't transfer."
- CSAT / satisfaction — how callers rate the experience. Containment with falling CSAT means you're trapping people; containment with steady or rising CSAT means you're genuinely helping.
Also watch average handle time, escalation rate and reasons, and first-contact resolution. The escalation reasons are gold: they show you exactly which intents to build next, turning your support line into a roadmap. For how these outcomes map to cost, see how much AI voice agents cost and our pricing.
When to hand to a human — as a matter of principle
The honest framing: AI phone support should handle the volume that is repetitive and structured, and route everything else to people. Emotional conversations, genuine judgment calls, high-stakes decisions, and anything outside the agent's competence belong with a human — and the system should route them there quickly and warmly. A platform that pretends the AI can do everything sets you up for angry callers and a damaged brand. A platform that draws the line clearly, and makes the human handoff seamless, gives you the best of both: zero hold time for the many, real people for the few who need them.
If you're evaluating this for your support line, our guides to choosing an AI voice agent and the broader customer support solution walk through the decision.
Written by Callaro Team
Field notes from the team building Callaro's voice AI platform.
Frequently asked questions
How does AI actually cut hold times to zero?+
Hold time is a capacity problem: calls arrive in bursts and human agents are a fixed resource, so queues form. An AI voice agent scales with concurrency instead of headcount, so a hundred simultaneous calls get a hundred simultaneous answers. There's no queue to build because there's no fixed pool to saturate, and routine calls are resolved end to end rather than waiting for a person.
What is tier-1 deflection in AI phone support?+
Tier-1 deflection means the AI agent fully resolves the high-frequency, low-nuance calls that dominate support volume — order status, hours, password resets, scheduling, balance checks. The critical part is real resolution via integration with your systems, not bouncing callers to a website or menu. Genuine self-service turns repetitive volume into containment.
Can AI phone support handle sudden call spikes?+
Yes. Route calls to the AI first, or overflow to it once human queues exceed a threshold, and spikes get absorbed by concurrency rather than building a queue. Your human team stays sized for steady-state volume while the AI takes the peaks from launches, outages, or billing runs.
What makes a good warm transfer to a human agent?+
The transfer must carry context: the human receives who the caller is, what they've tried, relevant account details, and a summary so far — so they pick up mid-context instead of asking the customer to repeat everything. This makes human agents more effective because every escalated call arrives pre-qualified and pre-summarized.
How do I measure whether AI support is working?+
Read containment and CSAT together. Containment (share of calls fully handled without a human) cuts cost and hold time, but only counts as successful resolution, not merely 'didn't transfer.' If CSAT falls as containment rises, you're trapping callers. Also track average handle time, first-contact resolution, and escalation reasons — the latter shows which intents to build next.
When should an AI agent hand a call to a human?+
Escalate on intents the agent isn't scoped for (complaints, retention-sensitive cancellations, complex disputes), detected frustration or repeated failure, an explicit request to speak to a person, and high-value or high-risk cases. Clear, fast escalation rules are what let you keep containment high without degrading the experience.
Related articles

Voice AI for BPOs and contact centers: sell outcomes, not seats
For a BPO, voice AI is a commercial decision before it's a technology one. Put the AI tier where clients get nothing today (overflow, after-hours, callbacks, quality review), price it on resolved outcomes, and work out your containment floor before you quote: a transferred call costs more than a human-only one, so break-even sits higher than most teams assume.

Omnichannel AI agents explained: test the seams, not the channel list
An omnichannel AI agent is one agent with one memory per customer, serving calls, WhatsApp, chat, SMS, RCS and email, and able to act across them mid-conversation. Every vendor now claims that, so the label tells you little. What separates platforms is the six seams where a journey crosses channels: identity, memory, action, events, people and consent. Here's what breaks at each, and how to test it.

Voice AI for home services: triage first, book second
In home services, a voice AI agent earns its place on the calls nobody can pick up, and its first job on those calls is triage, with booking second. Sort every call into one of four lanes (safety, emergency dispatch, routine booking, not a new job), give each its own ending, and design for the moment the on-call phone doesn't answer.
See the platform run a real call.
Book a demo and we'll show you outcomes executed end-to-end.
Book a demo